|
Shaoan Wang Algorithm Engineer at Light Origins I'm an algorithm engineer at Light Origins, working on embodied AI. I received my Ph.D. in 2026 from the School of Advanced Manufacturing and Robotics, Peking University, where I was advised by Prof. Junzhi Yu. During my Ph.D., I was a research intern at ByteDance Seed Robotics, and earlier at the embodied AI startup GALBOT, supervised by Prof. He Wang and Dr. Zhizheng Zhang. Before that, I completed my Bachelor's in Robotics at Beijing Institute of Technology in 2021, supervised by Prof. Huaping Wang. My research interests lie in embodied AI, with a specific focus on vision-language navigation and multimodal robot perception and planning. Earlier in my Ph.D., I worked on high-precision pose estimation for curved surfaces by leveraging visual fiducial markers. Email / Work Email / Google Scholar / GitHub |
|
News
|
Publications (Selected) |
|
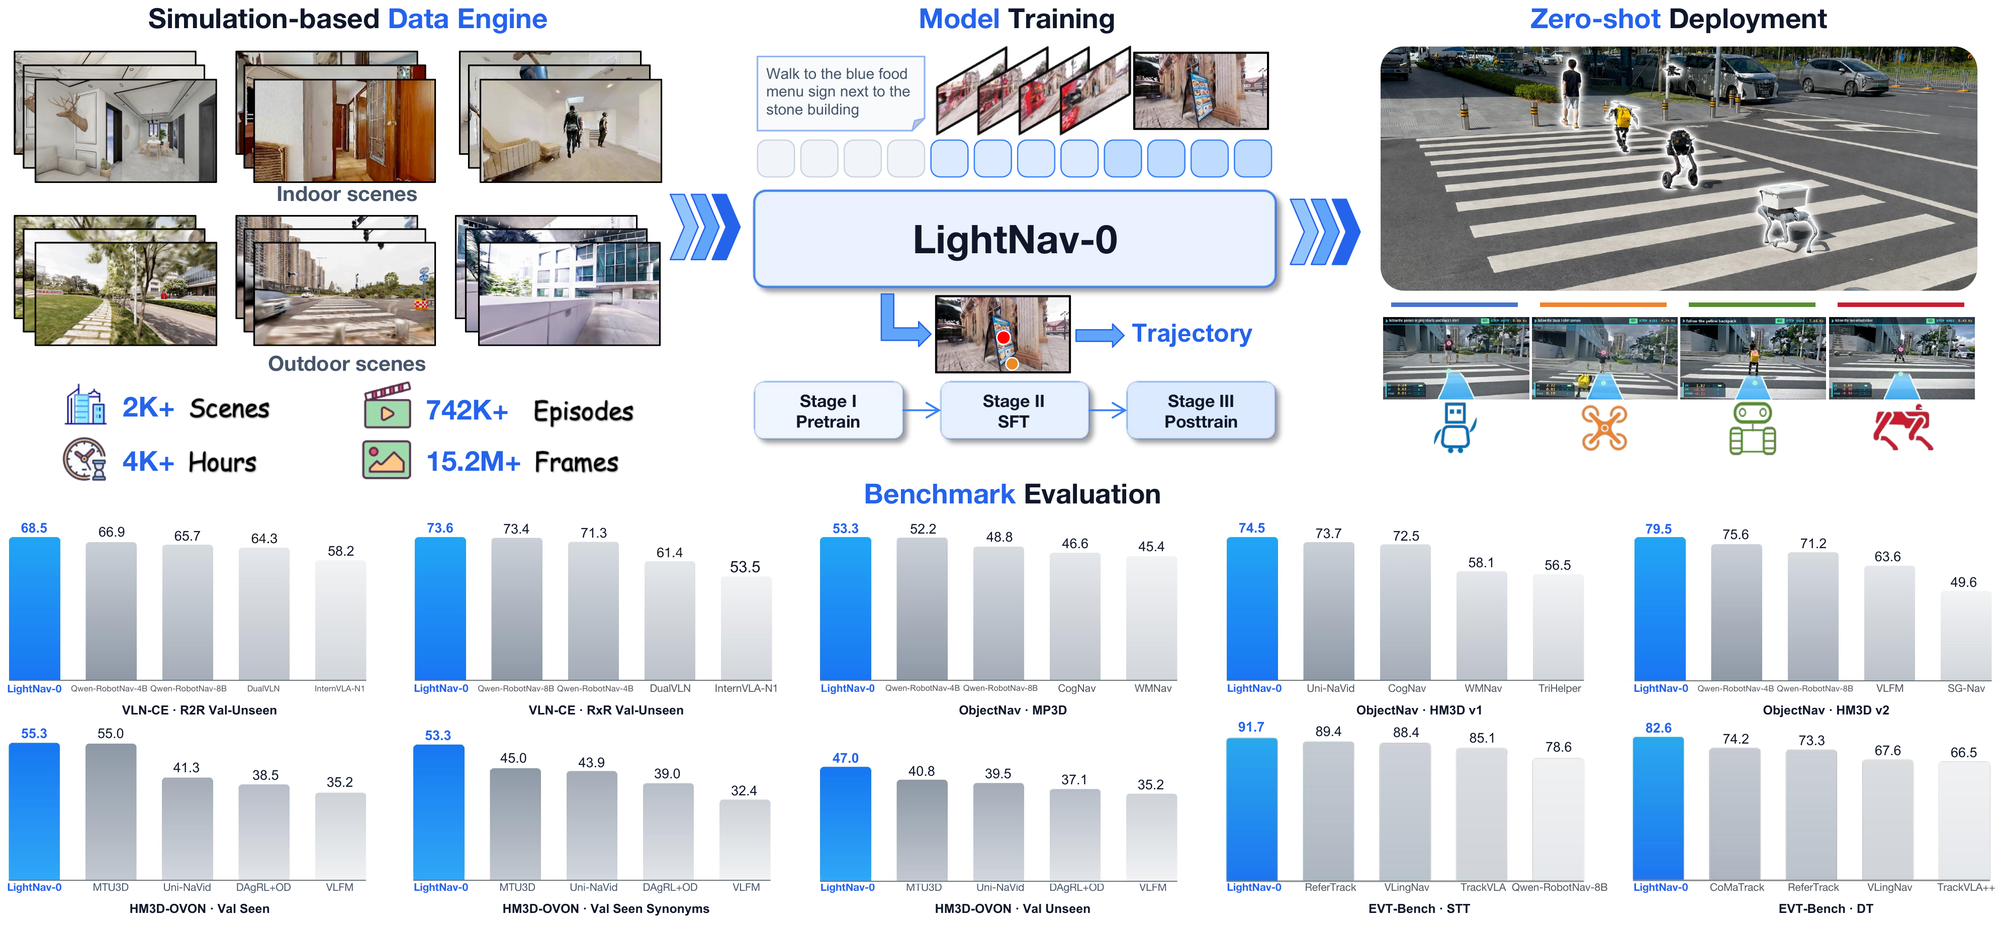
LightNav-0: Eliciting VLM Spatial Intelligence for Generalist Embodied Navigation
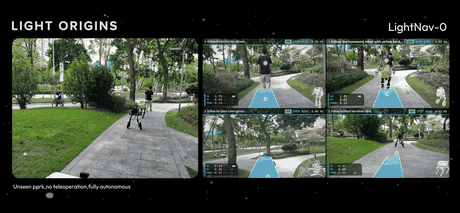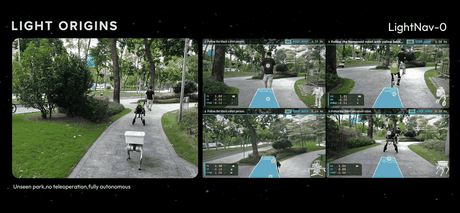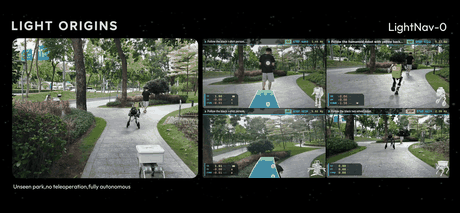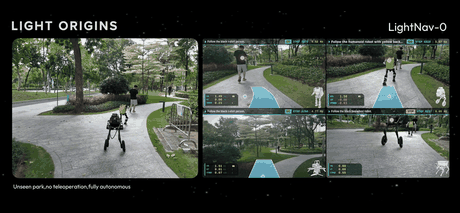
Shaoan Wang, Aocheng Luo, Fei Huang, Jingyi Xu, Xiaoyang Wang, Yueyu Wang, Qianli Ma, Fan Yang, Ran Mei, Jia Wei, Jiangpeng Hu, Xuhao Liu, Hongming Chen, Yuanbin Shao, Yiyang Lin, Ziliang Li, Liang Pan, Xinhang Liu, Yuntao Ma, Tingxiang Fan Technical Report [PDF] [Project page] [Code] LightNav-0 elicits the spatial intelligence of a pretrained vision-language model for generalist embodied navigation, following language instructions, searching for objects, and tracking visual targets with a single model. A unified token interface with dual-channel pointing and a residual vector-quantized action tokenizer lets it transfer zero-shot across embodiments and scenes without task-specific prediction heads. |
|
VLingNav: Embodied Navigation with Adaptive Reasoning and Visual-Assisted Linguistic Memory
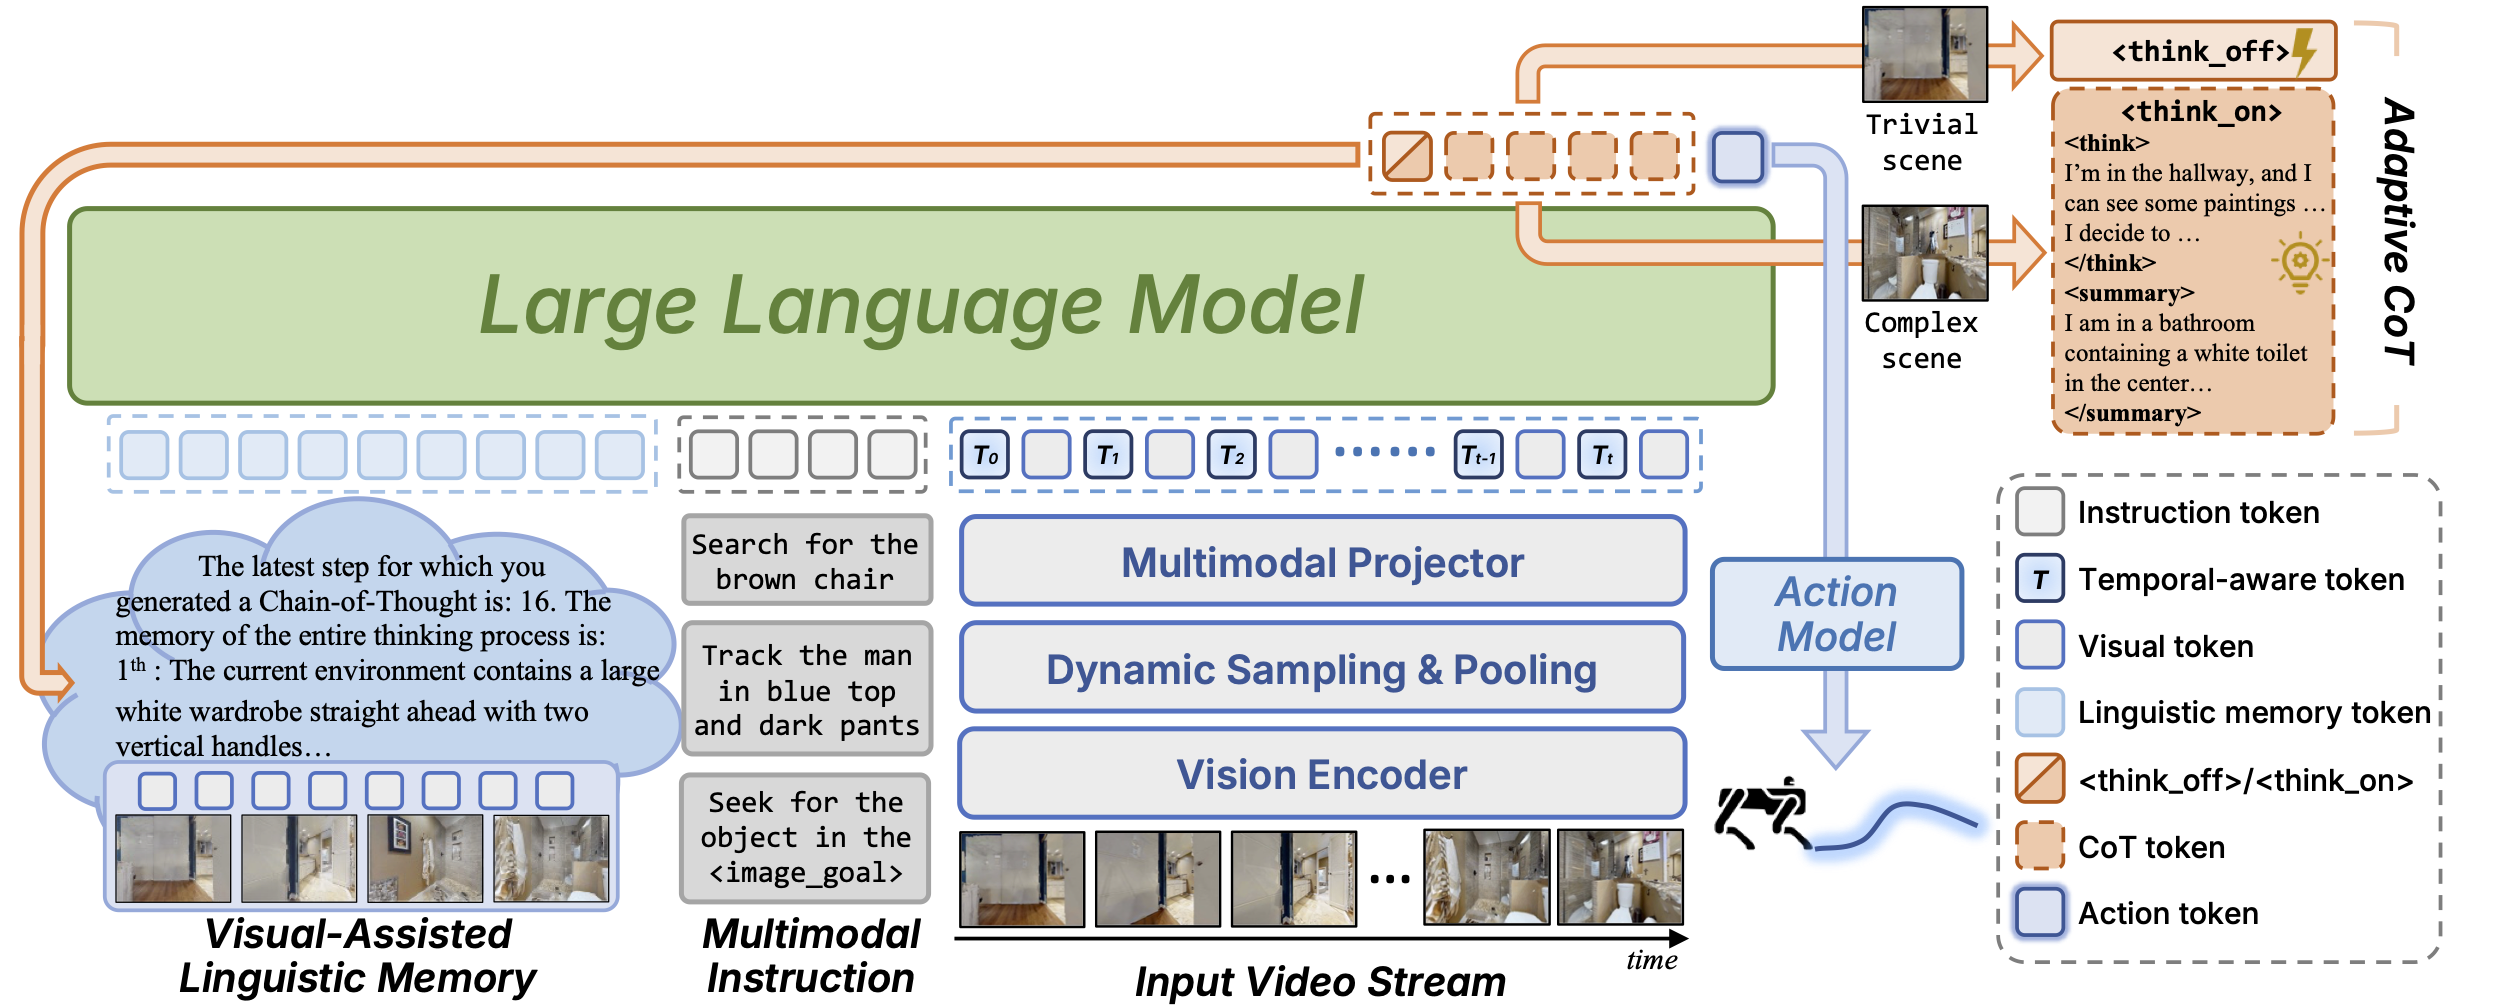
Shaoan Wang*, Yuanfei Luo*, Xingyu Chen†, Aocheng Luo, Dongyue Li, Chang Liu, Sheng Chen‡, Yangang Zhang, Junzhi Yu† arXiv Preprint [PDF] [Project page] VLingNav is a VLA model for embodied navigation that combines an adaptive chain-of-thought mechanism (AdaCoT) to trigger explicit reasoning only when needed with a visual-assisted linguistic memory module (VLingMem) to build persistent cross-modal semantic memory for long-horizon navigation. |
|
Embodied Navigation Foundation Model
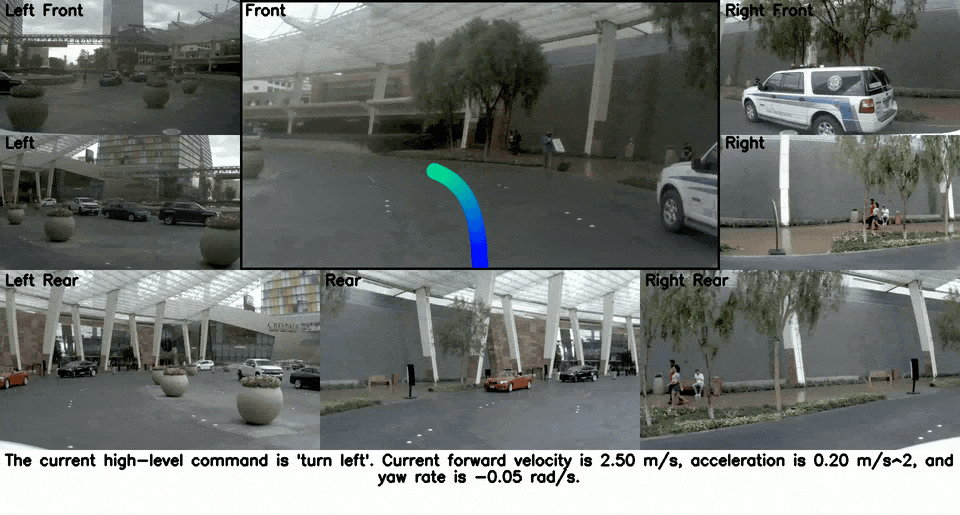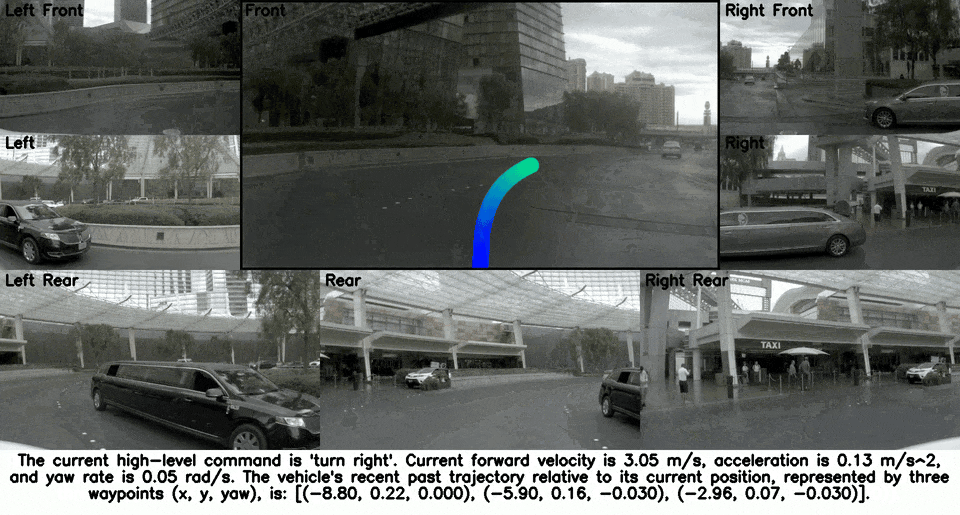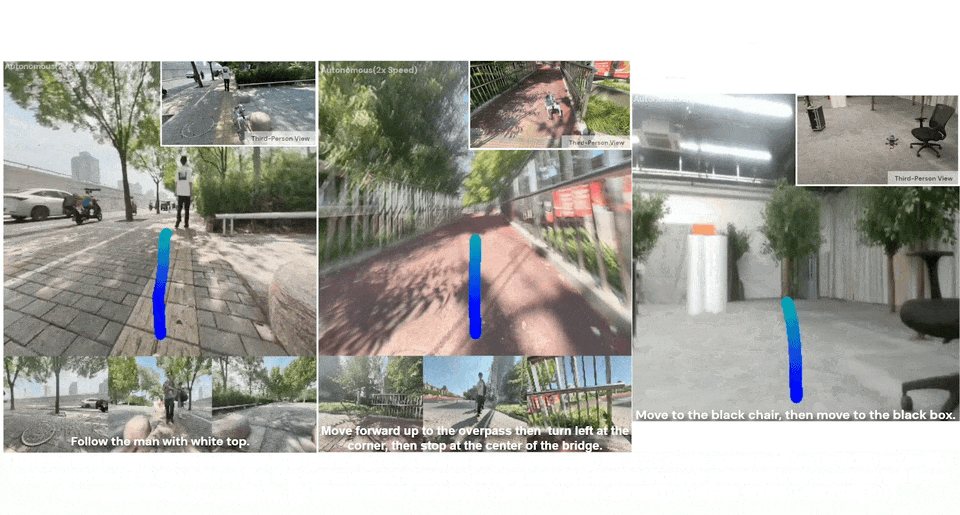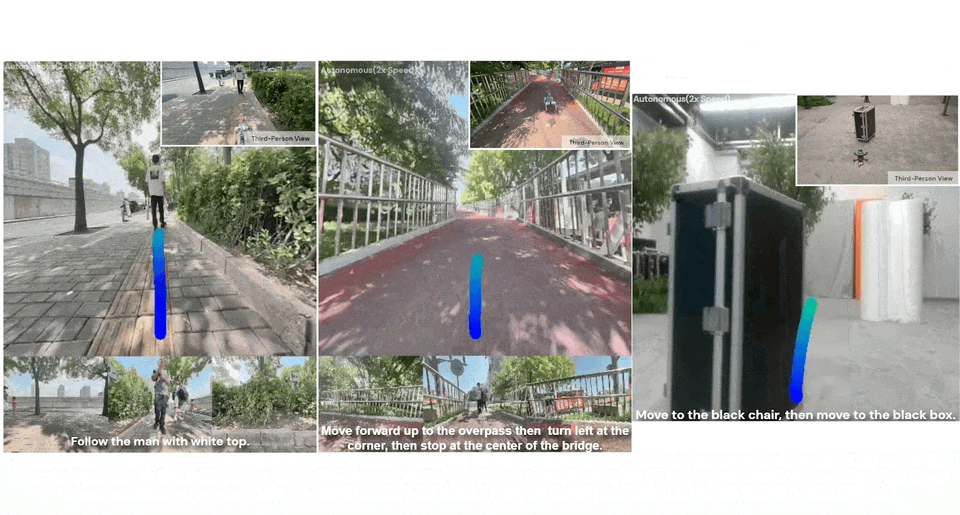
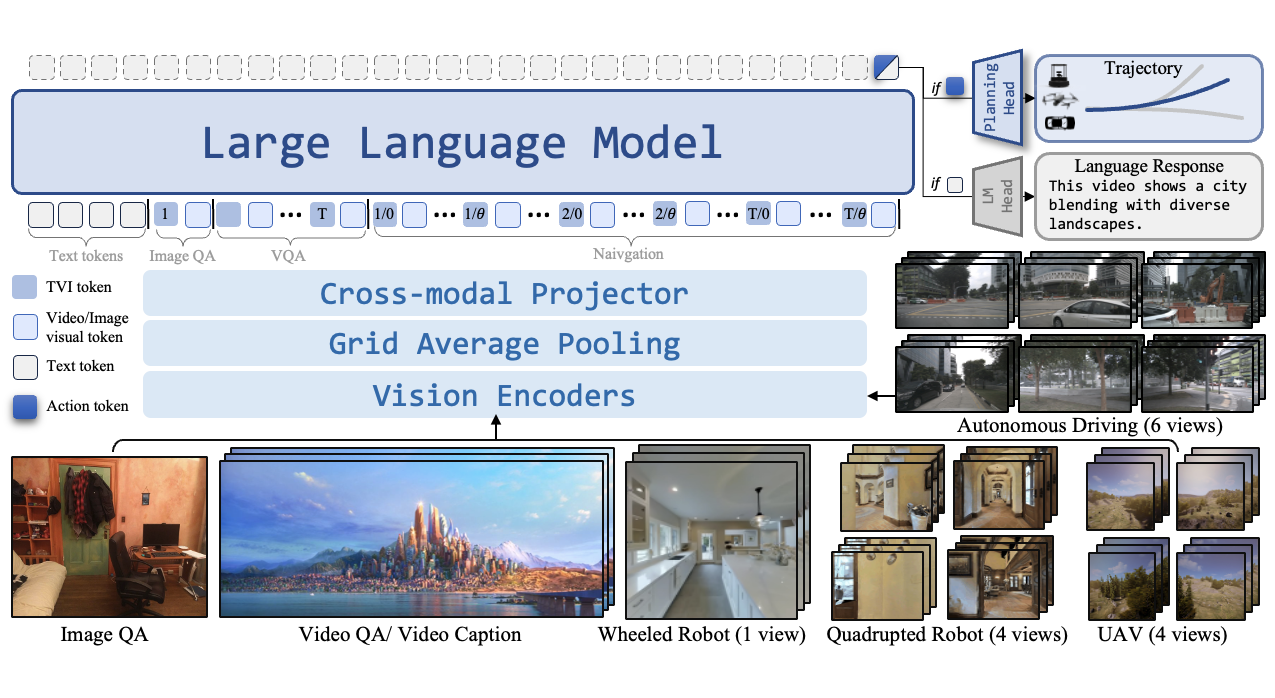
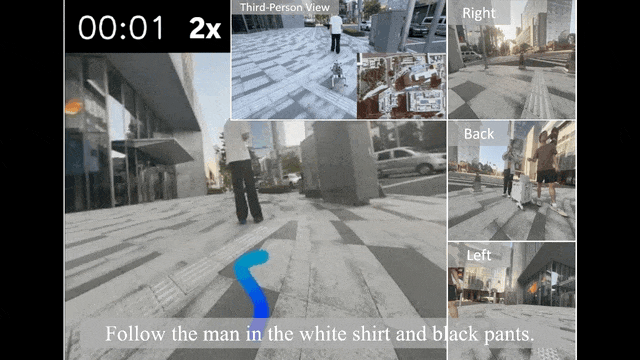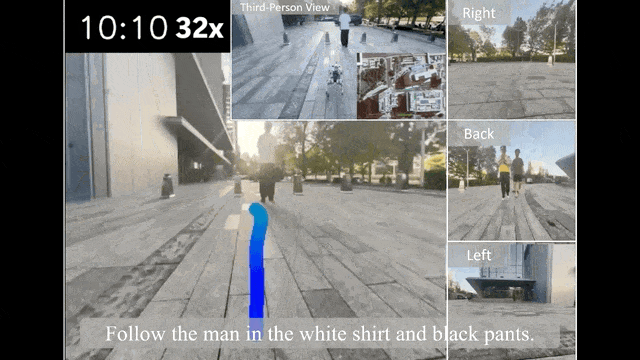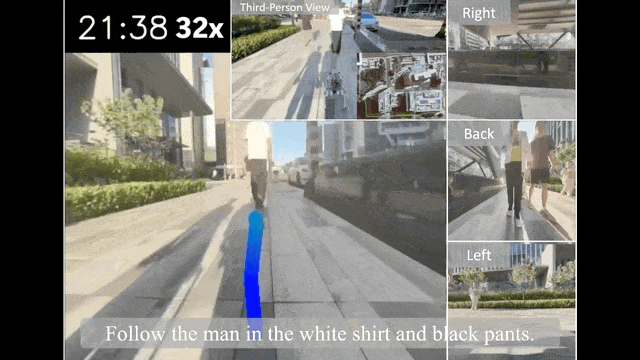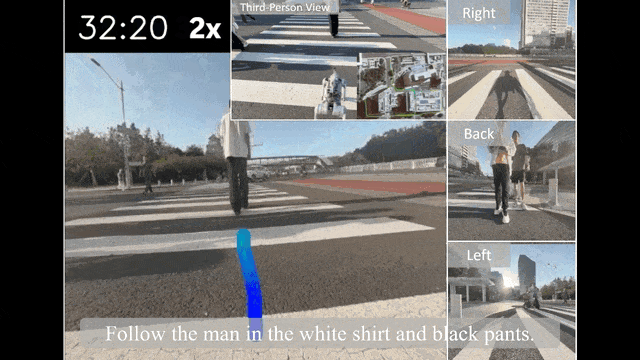
Jiazhao Zhang*, Anqi Li*, Yunpeng Qi*, Minghan Li*, Jiahang Liu, Shaoan Wang, Haoran Liu, Gengze Zhou, Yuze Wu, Xingxing Li, Yuxin Fan, Wenjun Li, Zhibo Chen, Fei Gao, Qi Wu, Zhizheng Zhang†, He Wang† ICLR 2026 [PDF] [Project page] We introduce a cross-embodiment and cross-task Navigation Foundation Model (NavFoM), trained on eight million navigation samples that encompass quadrupeds, drones, wheeled robots, and vehicles, and spanning diverse tasks such as vision-and-language navigation, object searching, target tracking, and autonomous driving. |
|
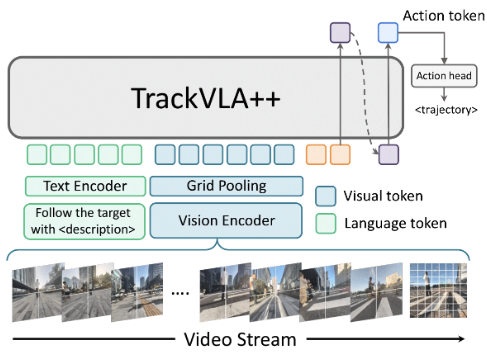
TrackVLA++: Unleashing Reasoning and Memory Capabilities in VLA Models for Embodied Visual Tracking
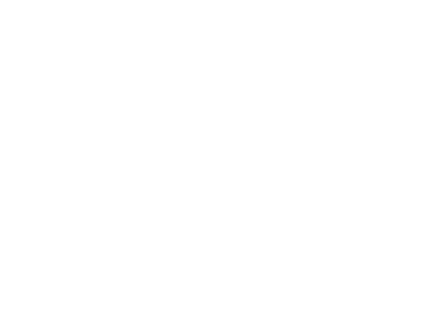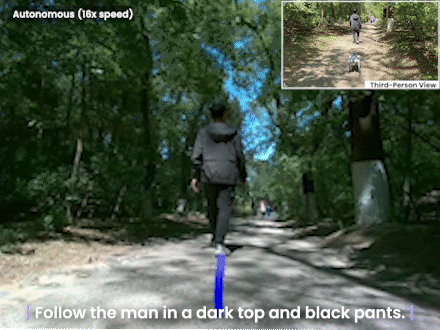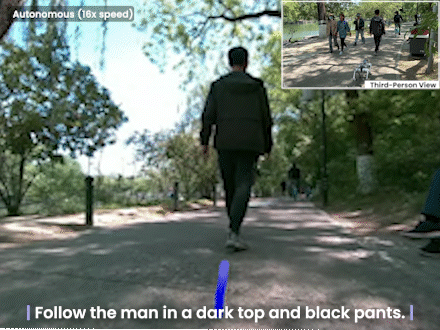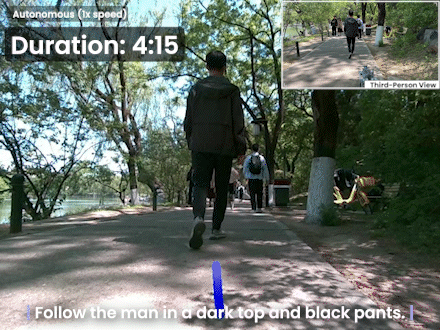
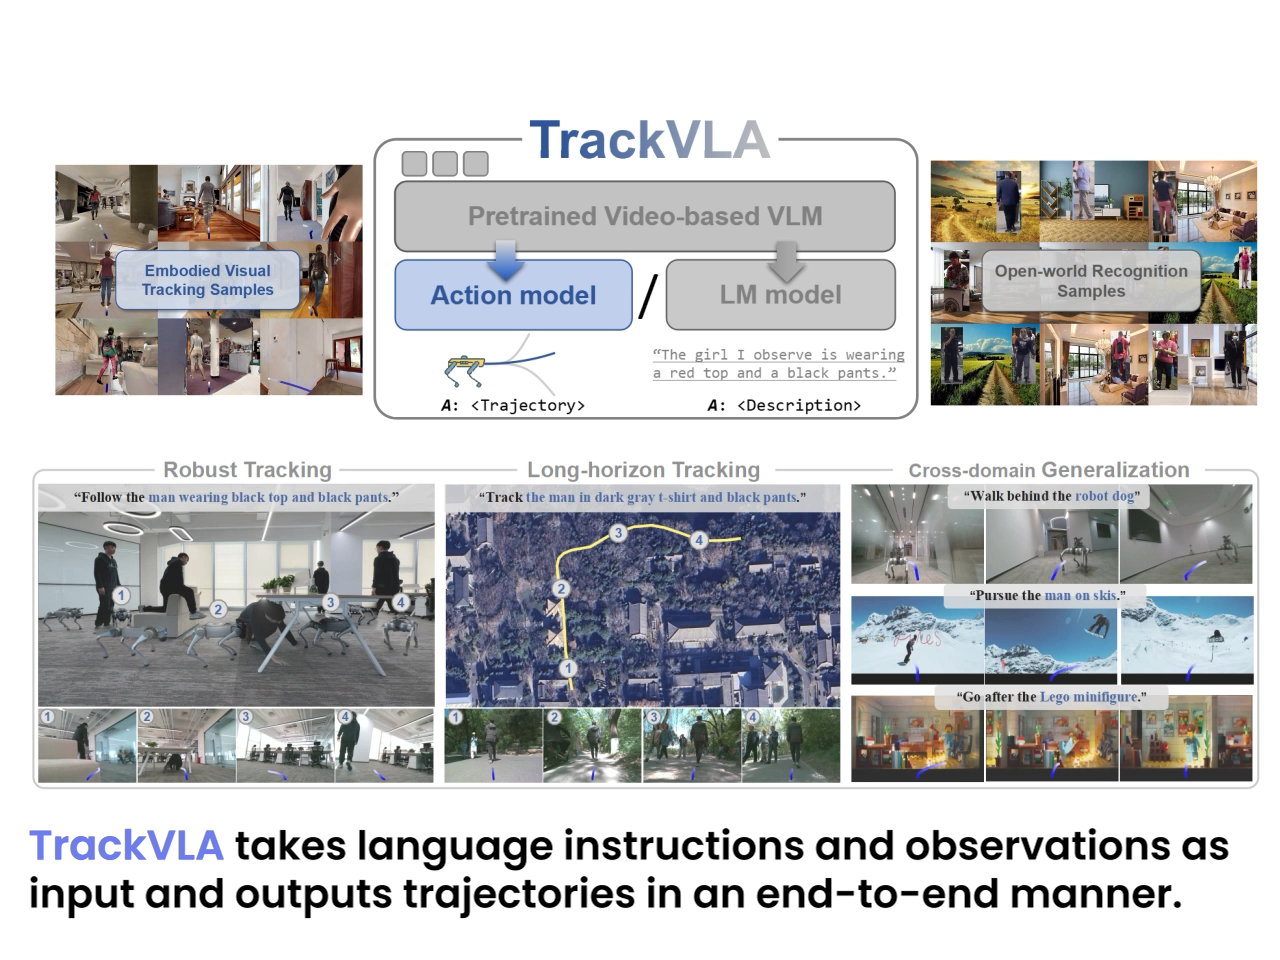
Jiahang Liu*, Yunpeng Qi*, Jiazhao Zhang*, Minghan Li, Shaoan Wang, Kui Wu, Hanjing Ye, Hong Zhang, Zhibo Chen, Fangwei Zhong, Zhizheng Zhang†, He Wang† ICRA 2026 [PDF] [Project page] TrackVLA++ is a novel Vision-Language-Action model that incorporates spatial reasoning and target identification memory, enabling superior performance in both long-horizon and highly crowded tracking scenarios. |
|
TrackVLA: Embodied Visual Tracking in the Wild
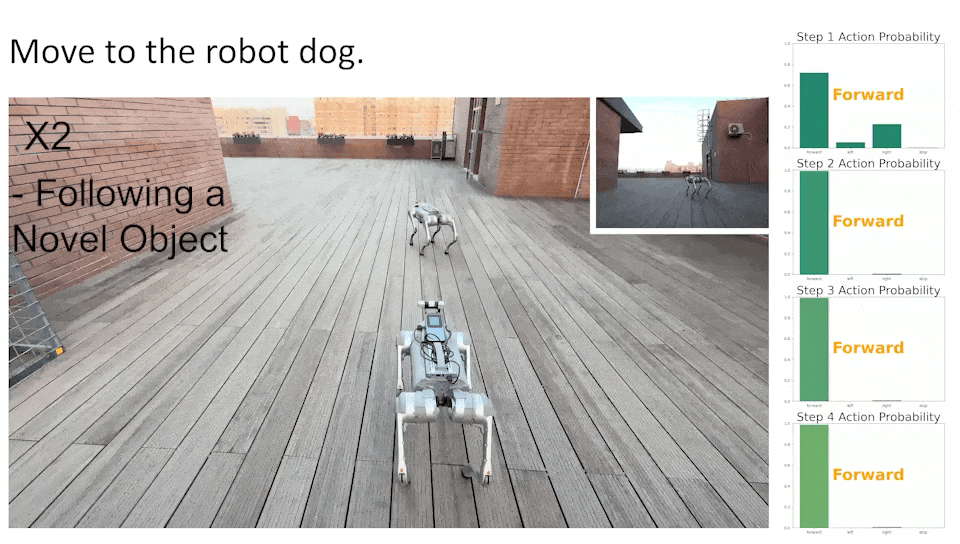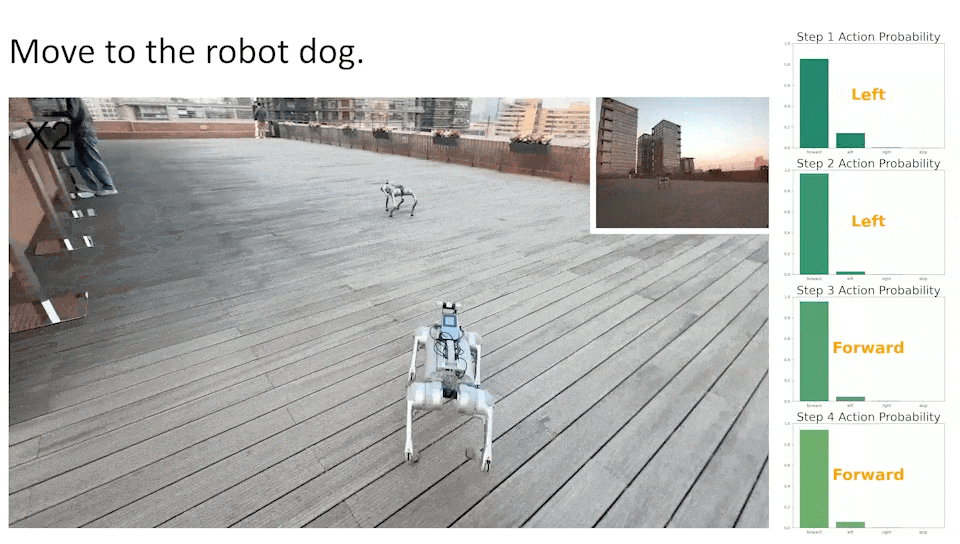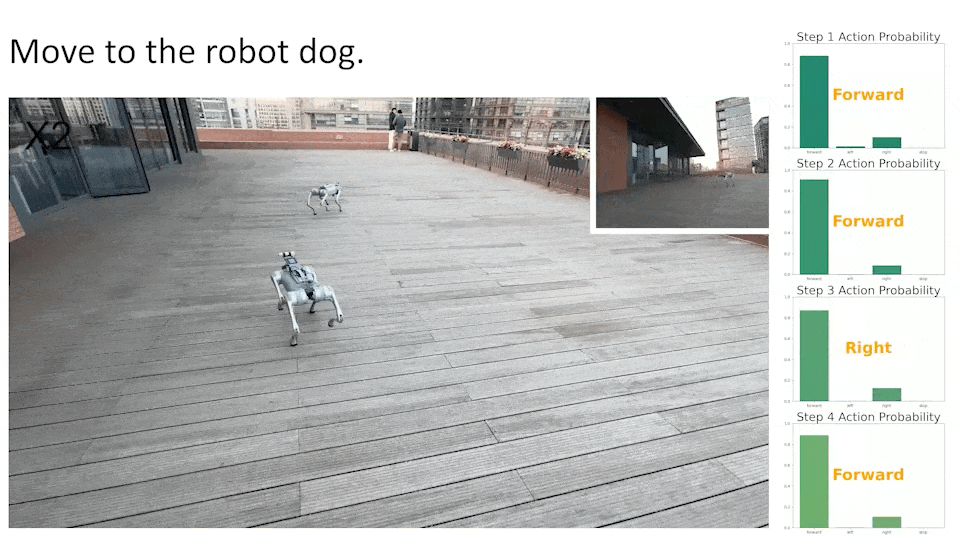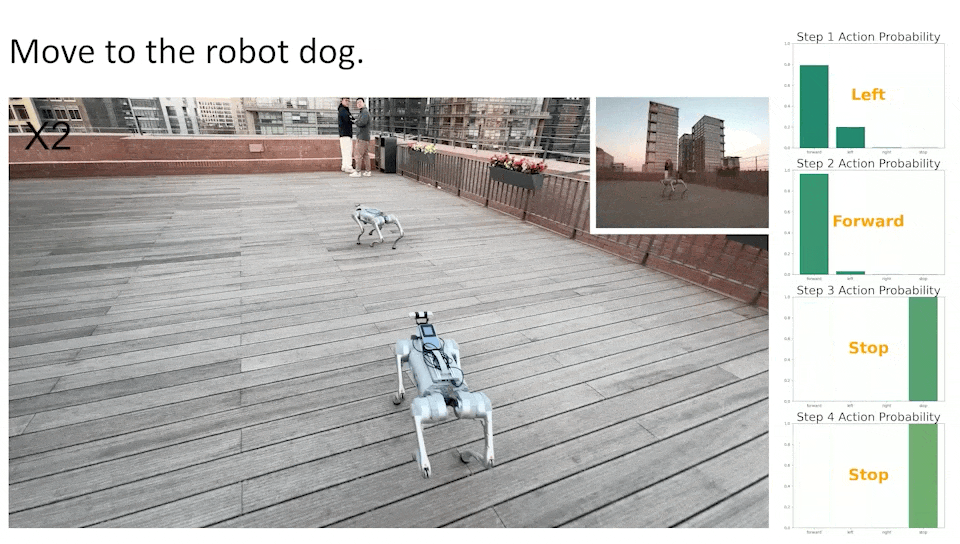
Shaoan Wang*, Jiazhao Zhang*, Minghan Li, Jiahang Liu, Anqi Li, Kui Wu, Fangwei Zhong, Junzhi Yu, Zhizheng Zhang†, He Wang† CoRL 2025 [PDF] [Project page] [Code & Benchmark] We present TrackVLA, a vision-language-action model capable of simultaneous object recognition and visual tracking, enabling zero-shot deployment in real-world scenarios. |
|
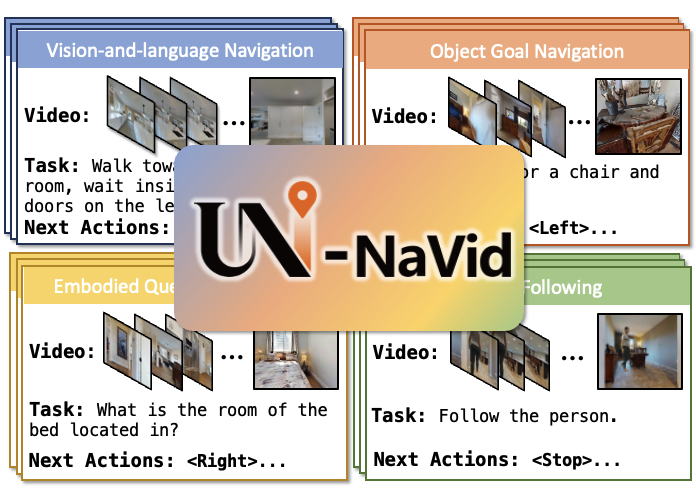
Uni-NaVid: A Video-based Vision-Language-Action Model for Unifying Embodied Navigation Tasks
Jiazhao Zhang, Kunyu Wang, Shaoan Wang (Core contributor), Minghan Li, Haoran Liu, Songlin Wei, Zhongyuan Wang, Zhizheng Zhang†, He Wang† RSS 2025 [PDF] [Project page] [Code] We present Uni-NaVid, the first video-based vision-language-action (VLA) model designed to unify diverse embodied navigation tasks and enable seamless navigation for mixed long-horizon tasks in unseen real-world environments. |
|
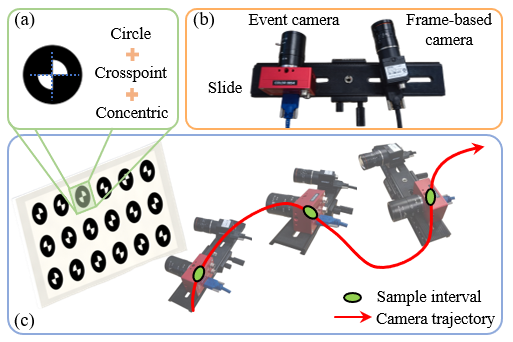
EF-Calib: Spatiotemporal Calibration of Event- and Frame-based Cameras Using Continuous-Time Trajectories
Shaoan Wang, Zhanhua Xin, Yaoqing Hu, Dongyue Li, Mingzhu Zhu, Junzhi Yu† IEEE Robotics and Automation Letters, 2024 [PDF] [BibTeX] [Code] A novel spatiotemporal calibration toolkit for event-based and frame-based camera system. |
|
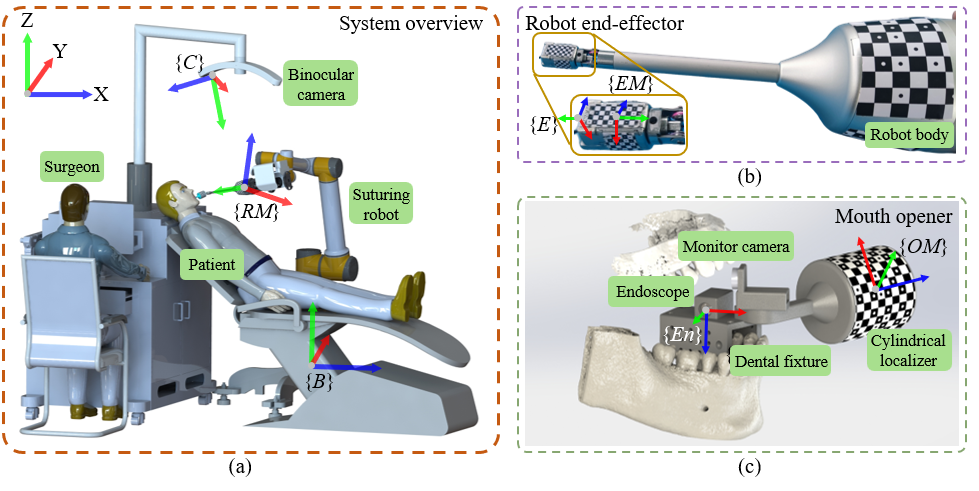
Spatially Compact Visual Navigation System for Automated Suturing Robot Toward Oral and Maxillofacial Surgery
Shaoan Wang, Qiming Zhao, Dongyue Li, Yaoqing Hu, Mingzhu Zhu, Fusong Yuan, Jinyan Shao, Junzhi Yu† IEEE Transactions on Instrumentation and Measurement, 2024 [PDF] [BibTeX] A spatially compact visual navigation system for autonomous OMS (Oral and Maxillofacial Surgery) suture robot. |
|
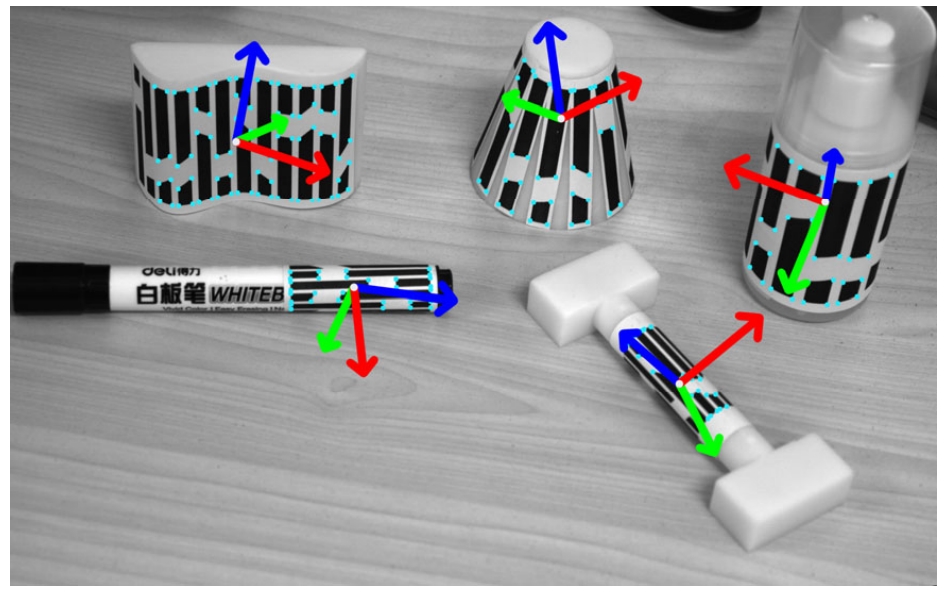
CylinderTag: An Accurate and Flexible Marker for Cylinder-Shape Objects Pose Estimation Based on Projective Invariants
Shaoan Wang, Mingzhu Zhu, Yaoqing Hu, Dongyue Li, Fusong Yuan, Junzhi Yu† IEEE Transactions on Visualization and Computer Graphics, 2024 [PDF] [BibTeX] [Code] A visual marker based on projective invariance called CylinderTag is developed, which provides a new solution for high-precision position estimation of curved objects. |
|
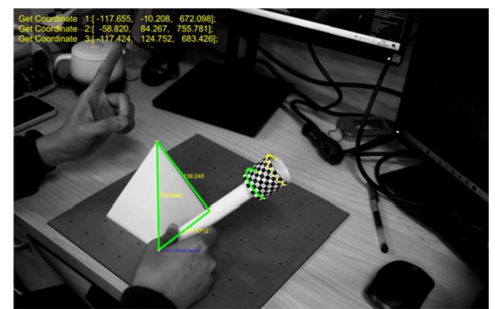
Accurate Detection and Localization of Curved Checkerboard-Like Marker Based on Quadratic Form
Shaoan Wang, Mingzhu Zhu, Yaoqing Hu, Dongyue Li, Fusong Yuan, Junzhi Yu† IEEE Transactions on Instrumentation and Measurement, 2022 [PDF] [BibTeX] [Code] A subpixel corner detector for curved checkerboard-like markers based on quadratic form. |